Your Kafka data as Iceberg.
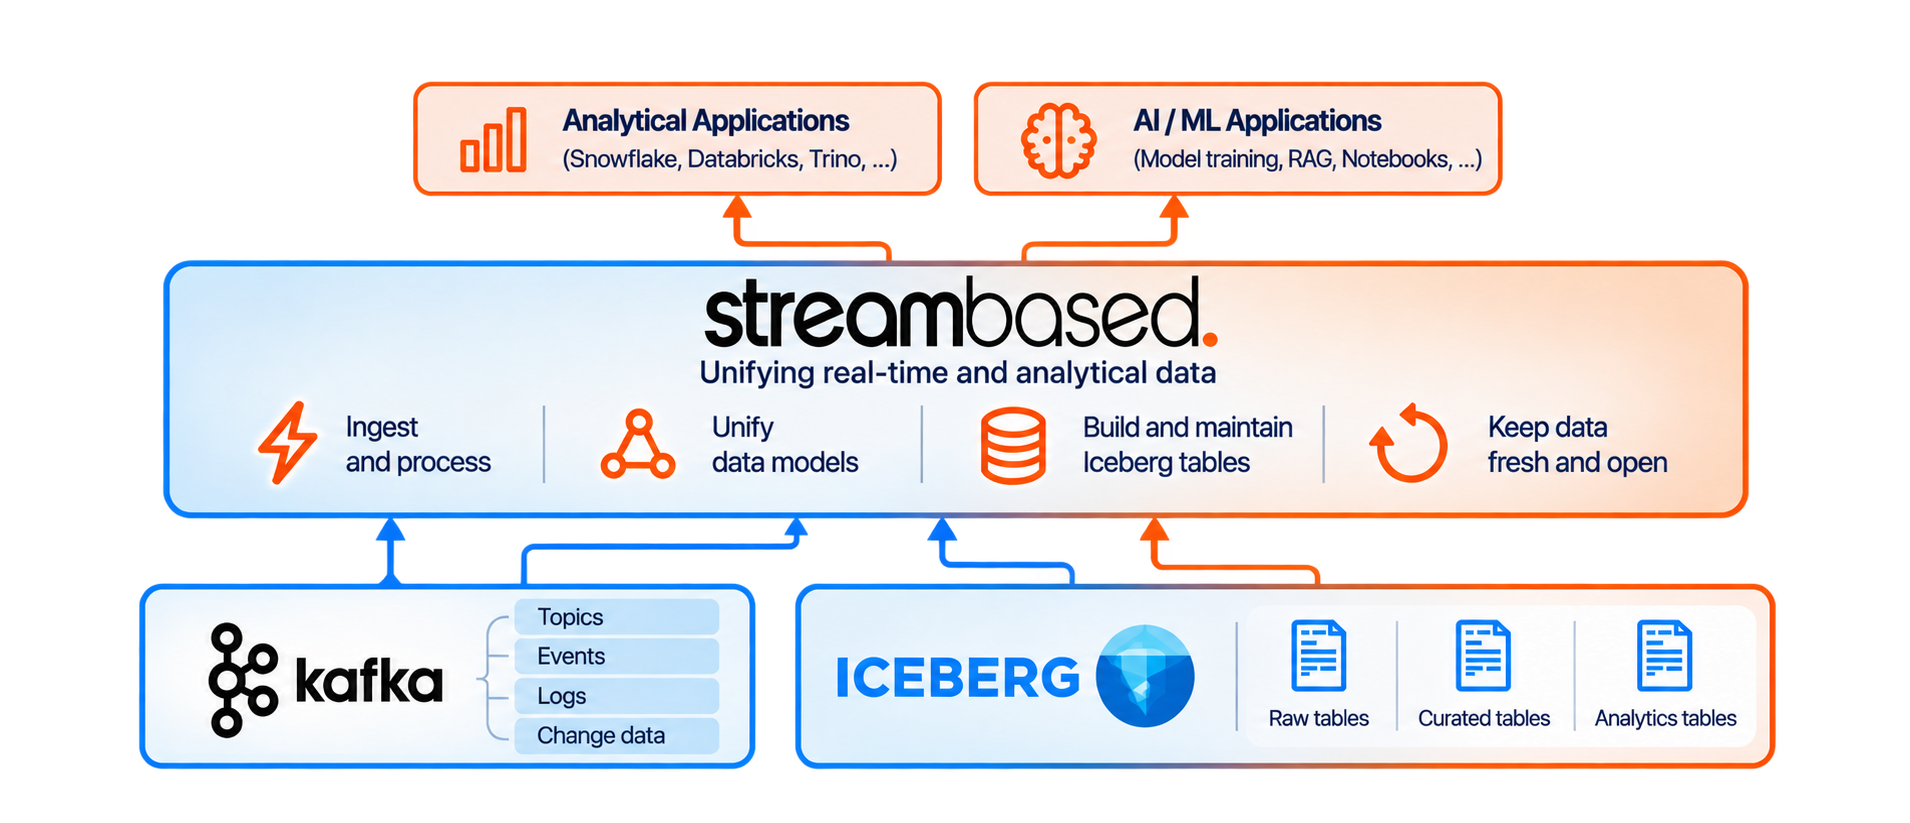
Streambased I.S.K. (Iceberg Service for Kafka) projects data from any Kafka-compatible platform directly as Apache Iceberg™ tables – instantly, without duplication, and queryable from any Iceberg engine.
What is Streambased I.S.K.
One continuous timeline
From the last millisecond to years of history
Applications shouldn't think in terms of "the stream" and "the warehouse." Instead they need a consistent view across time.
Drag the handle from the live edge back through years of archive — the same query keeps working, and Streambased picks HOT, UNIFIED, or COLD automatically.
- HOT reads the live stream in milliseconds
- UNIFIED spans stream and archive in one result
- COLD reaches years into compacted history
mode = HOT
Reading the live stream
now
p50 4 ms
Auto-playing·drag, tap a marker, or use ← → to take control.
Today: Pipelines unavailability and endless friction.
See what disappears
The usual path from an operational database to your analytics stack is a chain of steps. Streambased collapses it to a single view.
And don't forget to:
Every hop is another system to run, another copy to keep in sync, another place it can break.
What You Get with Streambased I.S.K.
The Freshest View
Data in Kafka is queryable in Iceberg the moment it lands. Dashboards, investigations and ML models always stay in step with the stream.
No Ops Overhead
No compaction jobs, no snapshot cleanup, no repartition rewrites. Data stays in Kafka, and Iceberg is just a logical view.
Unified Governance
Kafka's access rules, ACLs and retention windows carry over directly. The same policies apply whether you query a second ago or a year back.
Works With Your Stack
Runs on any Kafka distribution, plugs into any Iceberg engine (Trino, Spark, DuckDB, Snowflake, Databricks) and any catalog (Hive, Glue, Nessie).
Single Source of Truth
No duplication or drift. Kafka remains the system of record; Iceberg reflects it consistently for every client.
Instant Schema Evolution
When a schema changes in Kafka, it's instantly visible in Iceberg. No remapping, no rebuilds, no downtime.
Purpose-Built for Real-Time Analytics
Dashboards and Reporting
Keep dashboards and reports aligned with live data. Every Kafka topic is instantly available in Iceberg, so teams can query fresh events without waiting for pipelines to finish.
Machine Learning and AI
Models are never stale. Streambased projects Kafka topics as Iceberg tables, so feature stores and predictions are updated with the most recent data while retaining the full history.
Audit and Compliance
Retention windows and access controls carry over from Kafka. Auditors see the same policies applied consistently, from the most recent trade to years of archived activity.
Data Science Exploration
Queries combine today's activity with years of history in one place. Analysts and ML engineers can join and analyse streams with accuracy and freshness guaranteed.

Let's find the right solution for your data
We're here to help you unlock the full potential of your streaming data. Tell us about your challenges or ideas — and let's explore how Streambased can support your business.