Your Iceberg data as Kafka.
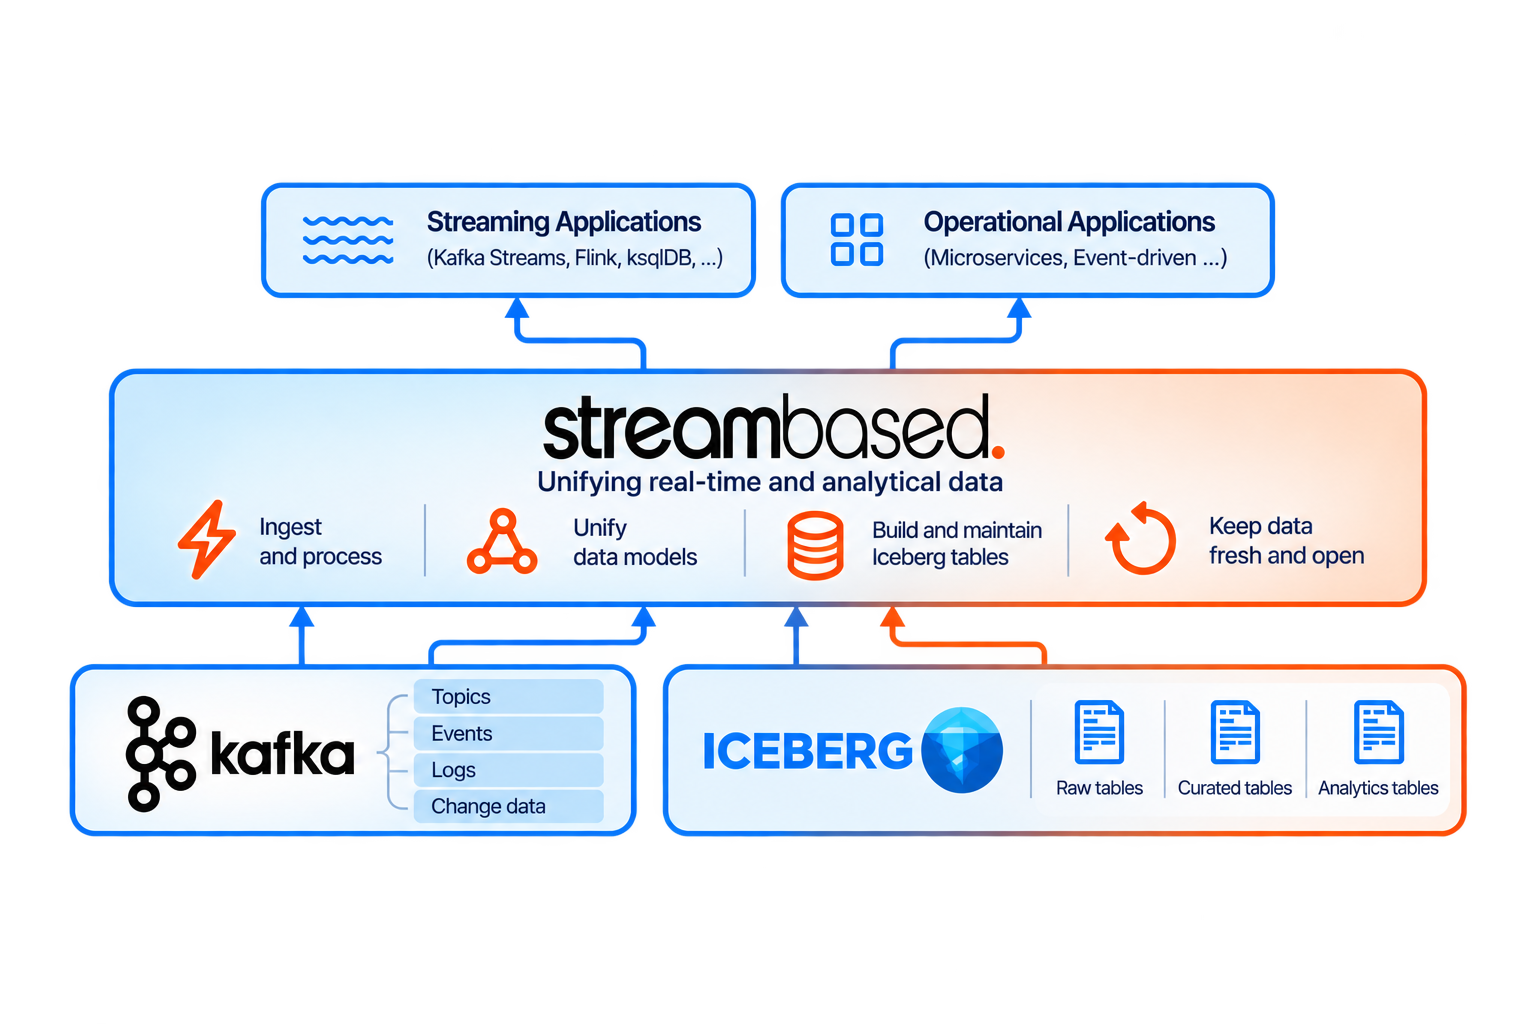
Streambased K.S.I. (Kafka Service for Iceberg) unifies long term storage in Apache Iceberg with recent data in Kafka to create a complete view for Kafka clients.
What is Streambased K.S.I.
Long retention cost reduction
Long term retention in Kafka is prohibitively more expensive
Kafka is built for speed, not cheap storage. Keeping years of events in Kafka means paying streaming-infrastructure prices for data that's rarely read.
Object storage flips the economics: it's built to retain massive datasets at a fraction of the cost. Compare Confluent Cloud with Amazon S3 Standard and Confluent storage comes out around 10x more expensive (a simplified comparison).
At scale, that difference adds up fast. Moving historical Kafka data to object storage lets you keep more data for longer, without paying Kafka prices to store it.
Cost vs value across retention
Pure Kafka: long-tail data is only available in Kafka. Its replay value is limited to rare circumstances, but the cost stays the same.
Beyond Kafka use cases
Kafka alone
OffsetOutOfRange
Data past retention has already been deleted.
With K.S.I.
Fetch → records returned
Served from Iceberg, through the same Kafka client.
What You Get with Streambased K.S.I
Cheap Infinite Retention
Store Kafka data forever in cost effective object storage. No more cost/retention compromises mean a richer/more resilient source for your Kafka applications.
No Connector Overhead
Remove deployment, maintenance and evolution overhead that surrounds traditional ETL based approaches to long term Kafka data storage.
Unified Governance
Apply the entire Kafka ecosystem (ACLs, quotas, schemas etc.) to your long term data and see instant updates on changes.
Works With Your Stack
Seamlessly integrates with any Kafka or Kafka compatible distribution (Confluent, Amazon MSK, Aiven etc.) and any Iceberg catalog (Polaris, Unity, LakeKeeper, Nessie).
Single Source of Truth
No duplication or drift. Events are stored only once as either Kafka or Iceberg ensuring no opportunity for inconsistencies can arise.
No Iceberg Maintenance
Combined with Streambased I.S.K., K.S.I.'s view based approach ensures that Iceberg is managed in a way that removes traditional maintenance requirements such as compaction and snapshot expiration.
More K.S.I wins
Breaking Kafka parallelism
Many of these cases are throughput, not latency bound. e.g. backfill requires a complete dataset to be loaded as quickly as possible. How fast the first message arrives doesn't matter. Typically, Iceberg engines are better suited to this kind of workload than Kafka: they run at a wider scale and they're optimized for bulk read.
Kafka
1 task per partition
K.S.I. + Iceberg engine
3 tasks per partition
Same 1.8M offsets. Each bar is one backfill task.
Reordering and filtering
This enables filtering, reordering and anything else.
SELECT * FROM orders
Mutable Kafka
Data Lake → Data Swamp. Event Stream → Event “Creek”? Long history, high volume. How do you remedy this for Kafka?
Duplicate
Stuck in the log
Bad record
Stuck in the log
PII
Stuck in the log
Purpose built for Streaming
- 01
Cost Reduction
Offload expensive Kafka storage to cheap and universal object storage. With K.S.I. Kafka provides a very small “hottest” storage with the majority of data stored in Iceberg.
- 02
State Hydration
Replay stream processing state from a complete dataset employing the complete Kappa architecture pattern.
- 03
Lagging Consumers
No longer can a lagging consumer drop off the end of retention and cause data loss. With K.S.I. consumers can access data all the way back to the beginning of time.
- 04
Kafka as a System of Record
Kafka, as the typical entry point into an organisation's data estate, is the ideal system of record for data. With K.S.I. this capability can finally be realized providing the single source of truth for ingested data.

Let's find the right solution for your data
We're here to help you unlock the full potential of your streaming data. Tell us about your challenges or ideas — and let's explore how Streambased can support your business.